- Click Local model in the left navigation.
- Choose a model folder. You can use the same folder as HaoOne if you already have its models.
- Choose an accessible download source, download a transcription model, and wait for Installed.
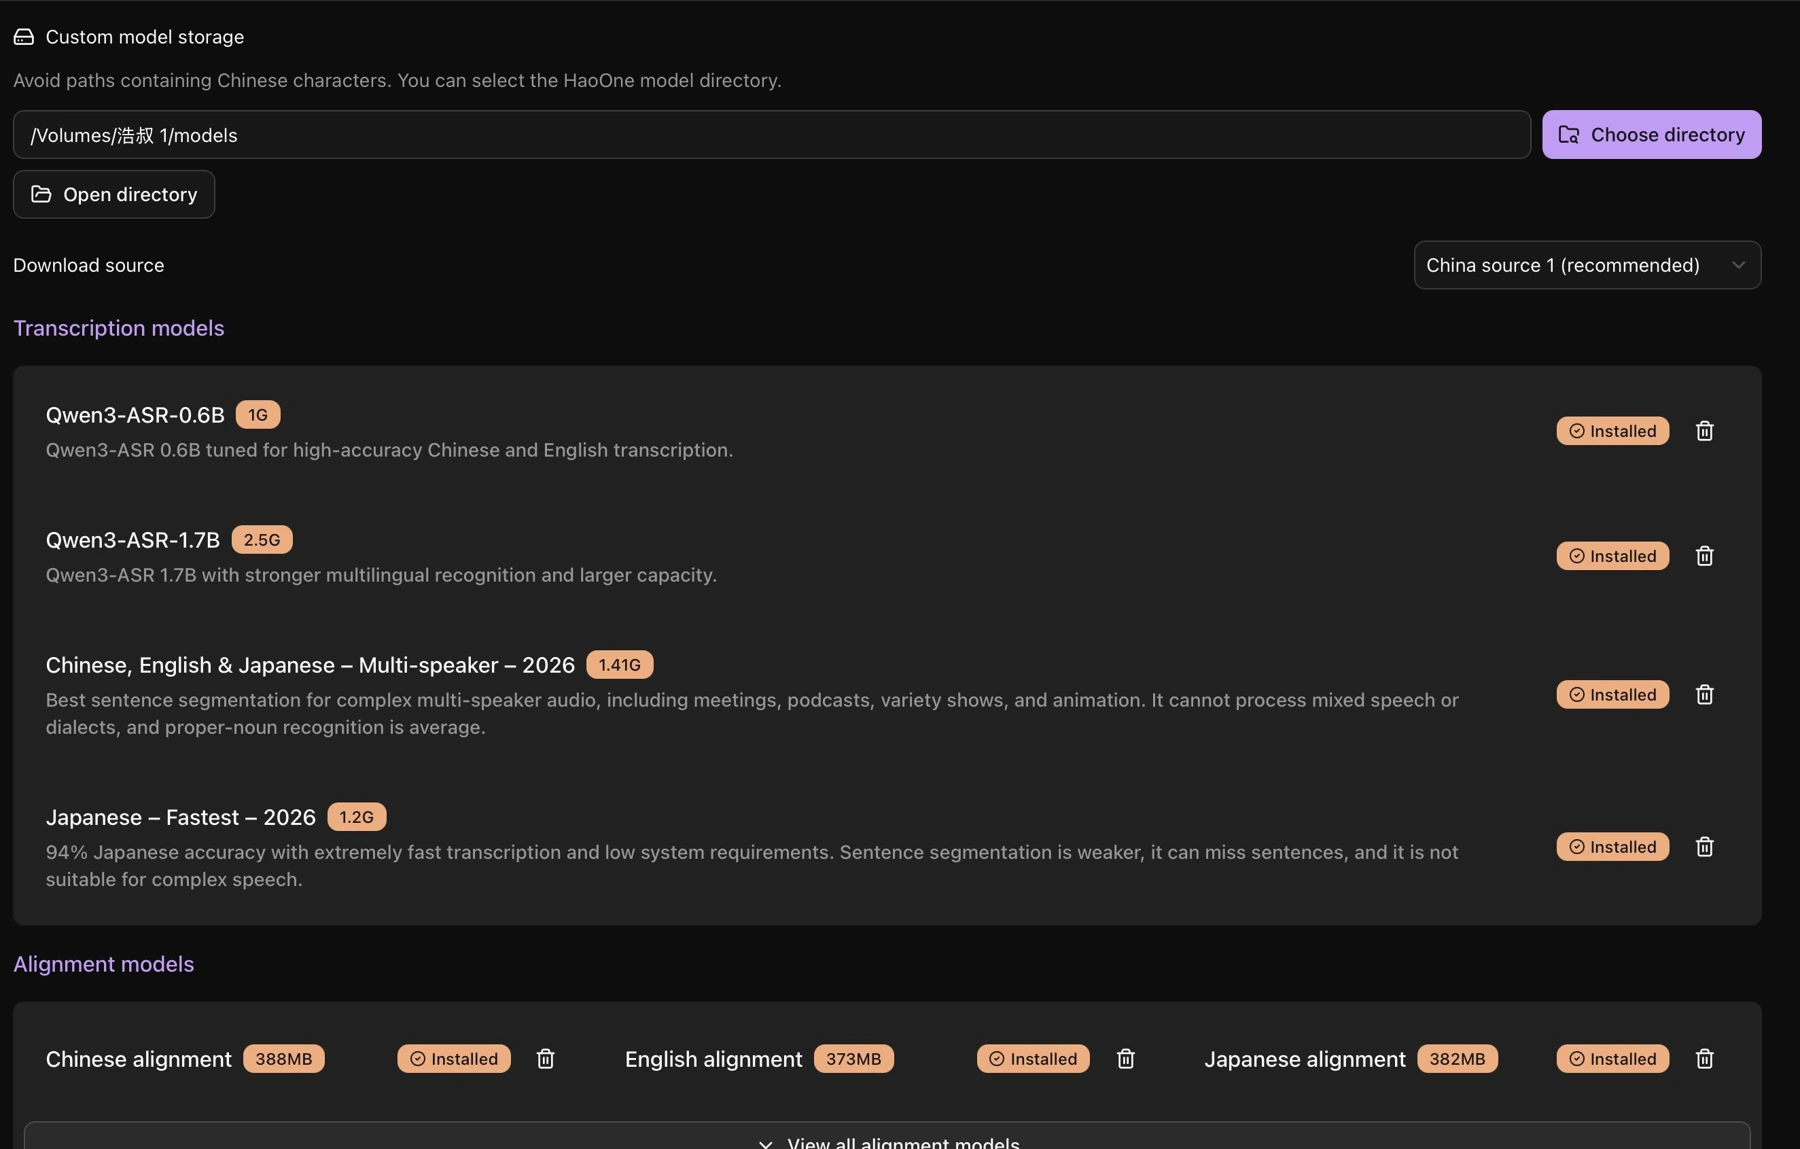
Start with Qwen3-ASR-0.6B for a lighter model, or choose Qwen3-ASR-1.7B when recognition quality matters more.
- Check that the alignment model for your media language is installed.
- Install WeSpeaker to identify speakers. For semantic search, install both the text embedding model and the reranking model.
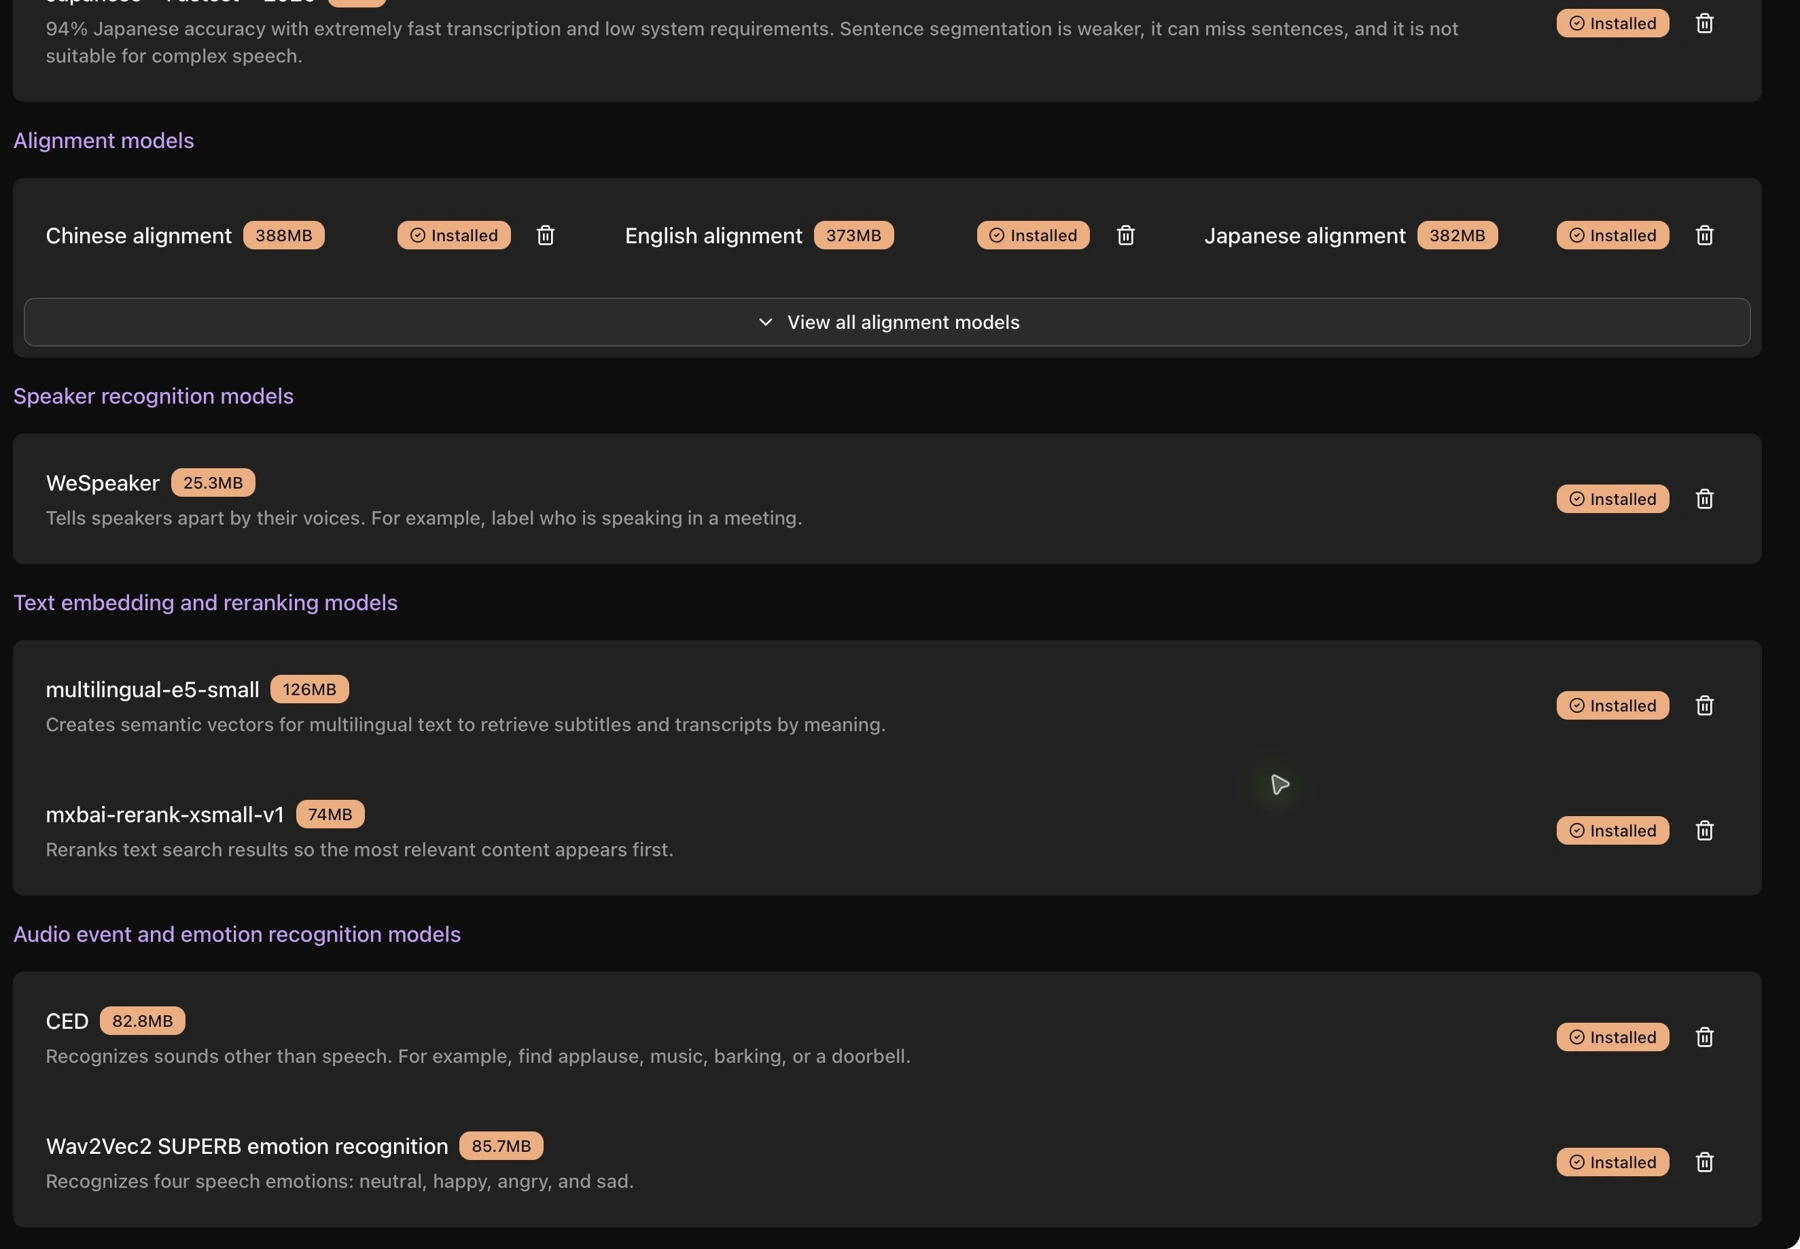
Download the emotion and audio-event models if you need those recognition options.